NVIDIA DGX Spark
SGLang · MXFP4
openai/gpt-oss-120bNVIDIA source Run gpt-oss-120b locally
OpenAI’s open-weight mixture-of-experts model: 117B parameters in total, 5.1B active per token. It ships in MXFP4, so the weights need about 70 GB and a 128 GB machine can hold it.
Short answer
24 of 24 catalogued workstations pass the memory screen at 4-bit. The cheapest with a public price is the Framework Desktop · Ryzen AI Max+ (≈ $3.4k). On the NVIDIA DGX Spark, memory bandwidth caps one request at ≤ 77 tok/s. Documented recipes exist for NVIDIA GB10, NVIDIA RTX PRO.
| Machine | Memory | Needed at 4-bit | Speed ceiling | Highest precision that fits | Recipe | List price |
|---|---|---|---|---|---|---|
 Framework Desktop · Ryzen AI Max+AMD Ryzen AI Max | 128 GB | 80 GB Fits | Bandwidth not in record | 4-bit | ≈ $3.4k | |
 MINISFORUM MS-S1 MAXAMD Ryzen AI Max | 128 GB | 80 GB Fits | Bandwidth not in record | 4-bit | ≈ $3.8k | |
 NVIDIA DGX SparkNVIDIA GB10 | 128 GB | 80 GB Fits | ≤ 77 tok/s | 4-bit | Vendor-listed validationSGLang · MXFP4 | ≈ $4.7k |
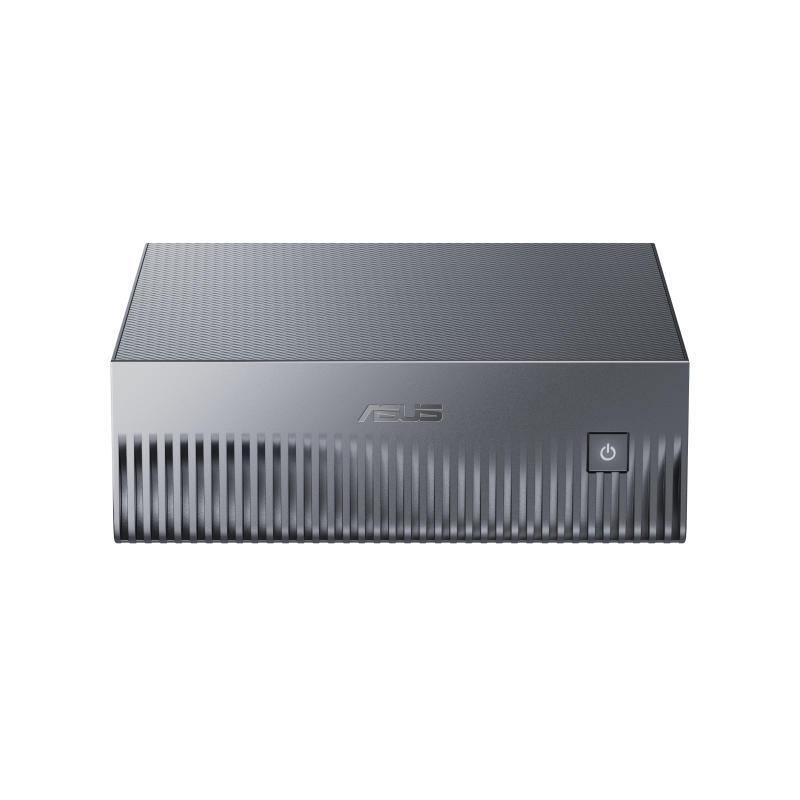 ASUS Ascent GX10NVIDIA GB10 | 128 GB | 80 GB Fits | ≤ 77 tok/s | 4-bit | Vendor-listed validationSGLang · MXFP4 | ≈ $5.3k |
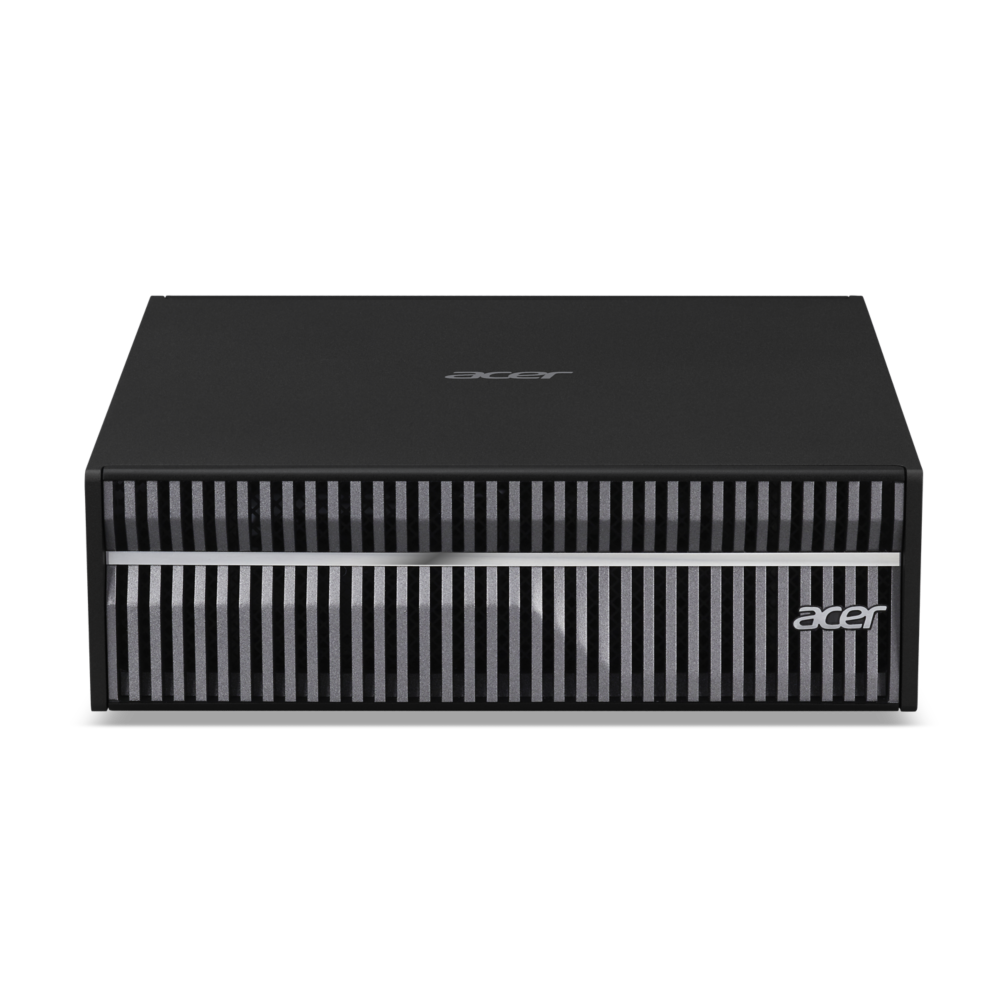 Acer Veriton GN100NVIDIA GB10 | 128 GB | 80 GB Fits | ≤ 77 tok/s | 4-bit | Vendor-listed validationSGLang · MXFP4 | ≈ $5.5k |
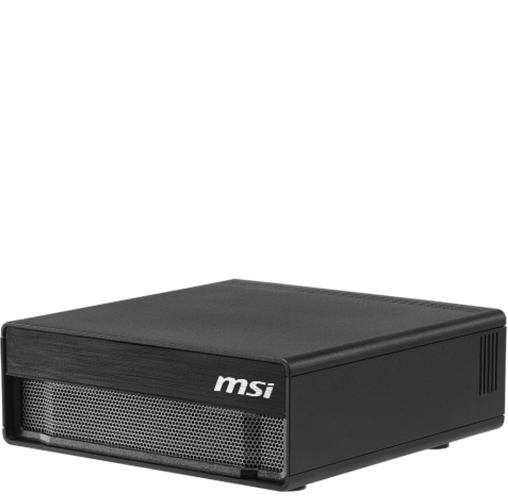 MSI EdgeXpertNVIDIA GB10 | 128 GB | 80 GB Fits | ≤ 77 tok/s | 4-bit | Vendor-listed validationSGLang · MXFP4 | ≈ $6k |
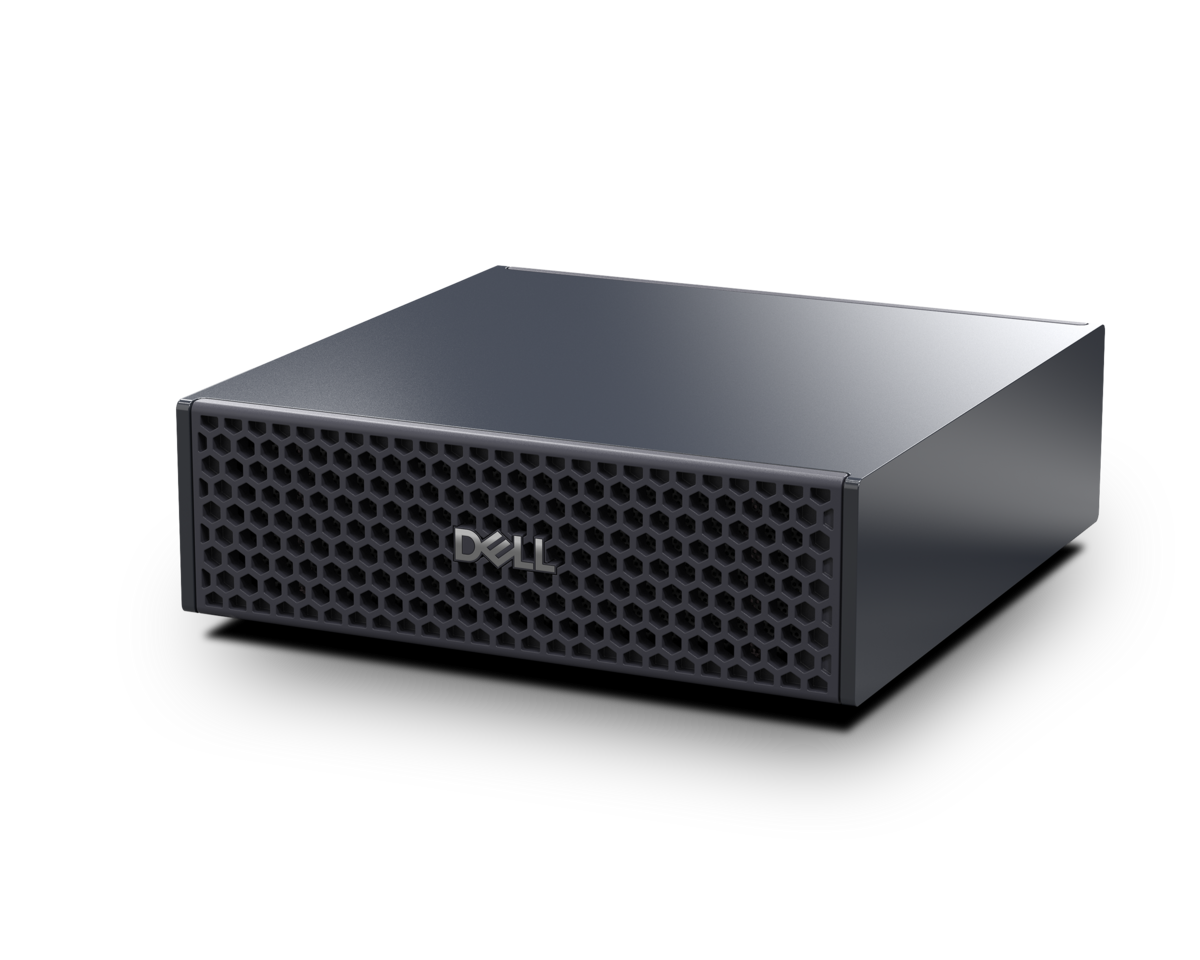 Dell Pro Max with GB10NVIDIA GB10 | 128 GB | 80 GB Fits | ≤ 77 tok/s | 4-bit | Vendor-listed validationSGLang · MXFP4 | ≈ $8.2k |
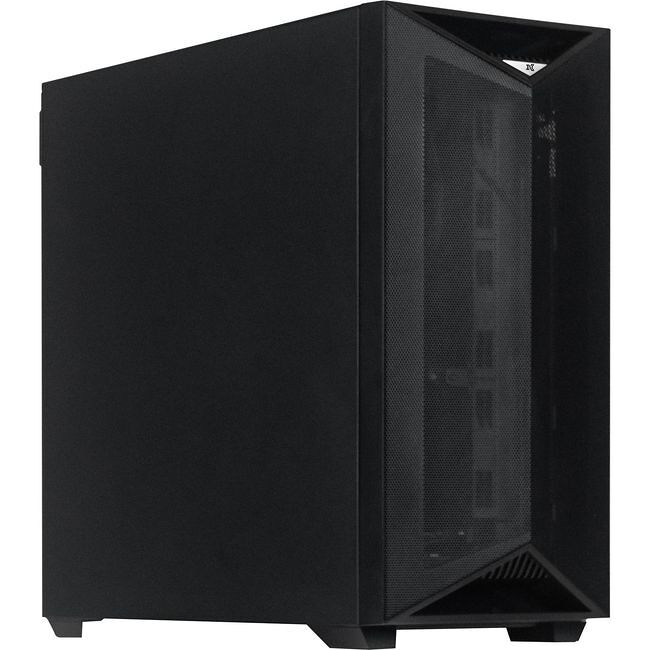 Exxact Valence DGX StationNVIDIA GB300 | 252 GB | 76 GB Fits | ≤ 2008 tok/s | 4-bit | ≈ $95k | |
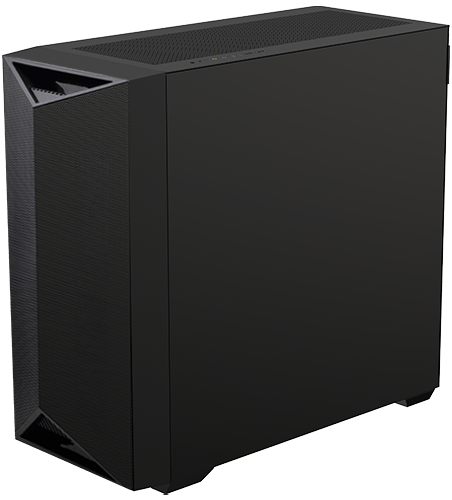 MSI XpertStation WS300NVIDIA GB300 | 252 GB | 76 GB Fits | ≤ 2008 tok/s | 4-bit | ≈ $109k | |
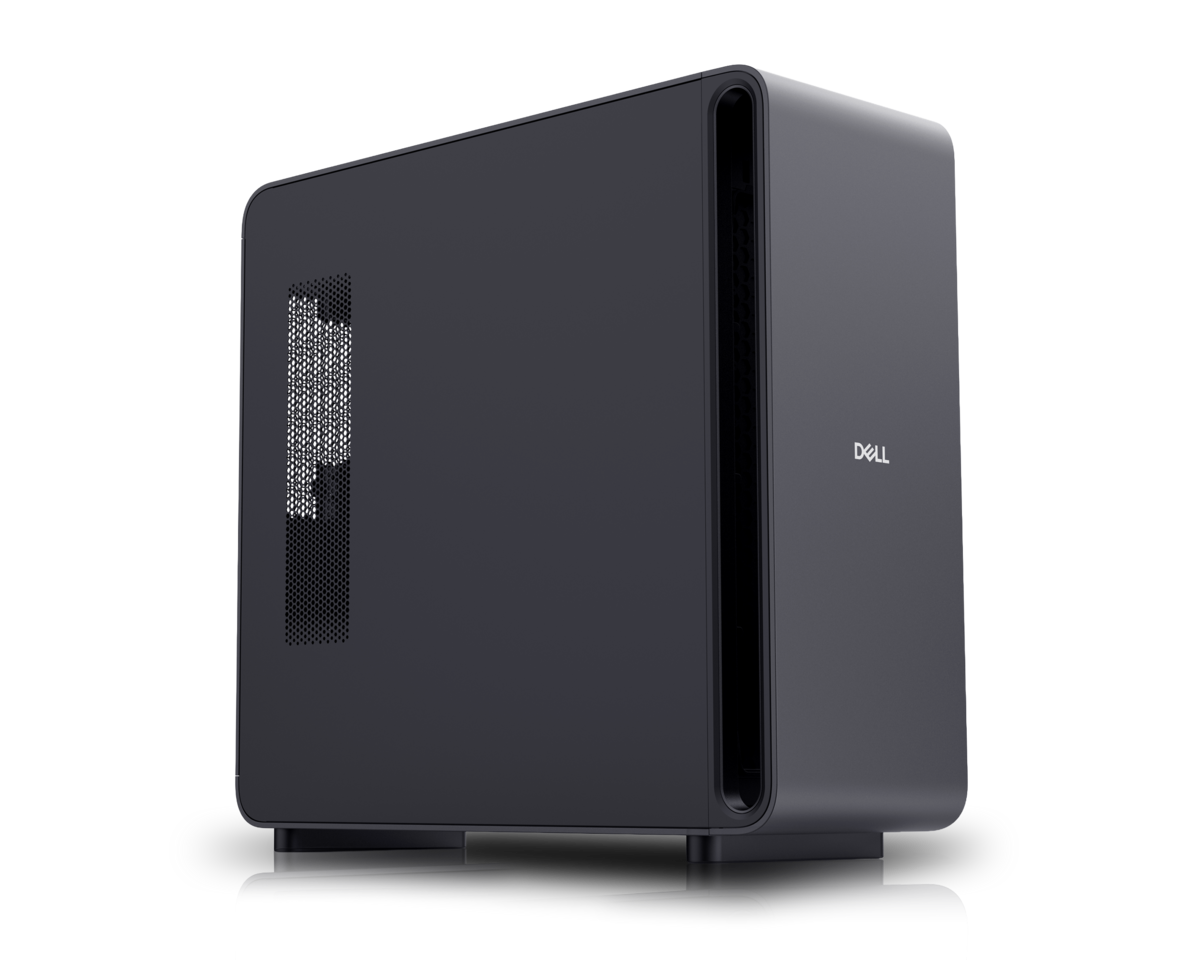 Dell Pro Max with GB300NVIDIA GB300 | 252 GB | 76 GB Fits | ≤ 2008 tok/s | 4-bit | ≈ $175k | |
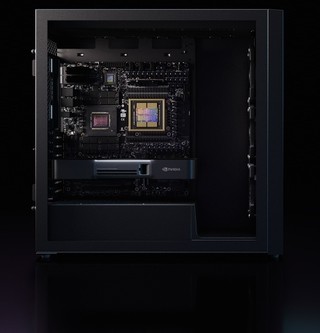 NVIDIA DGX StationNVIDIA GB300 | 252 GB | 76 GB Fits | ≤ 2008 tok/s | 4-bit | Price from the manufacturer | |
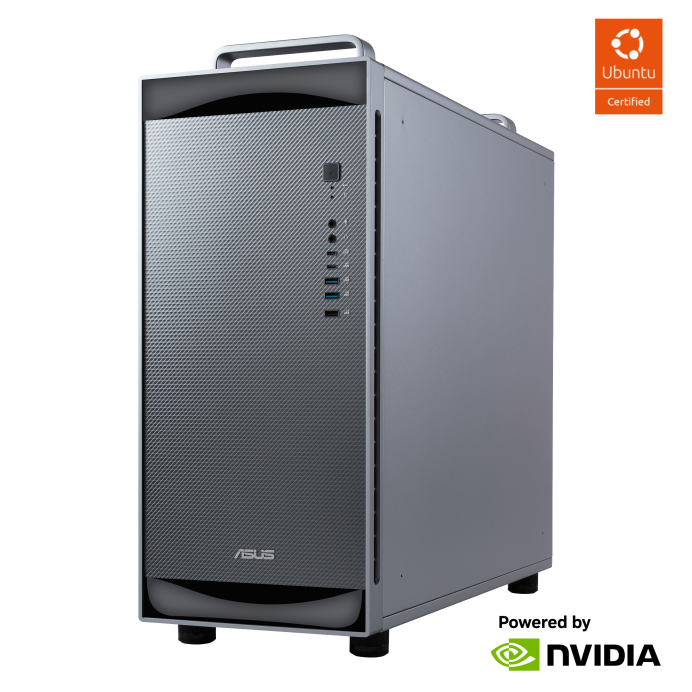 ASUS ExpertCenter Pro ET900N G3NVIDIA GB300 | 252 GB | 76 GB Fits | ≤ 2008 tok/s | 4-bit | Price from the manufacturer | |
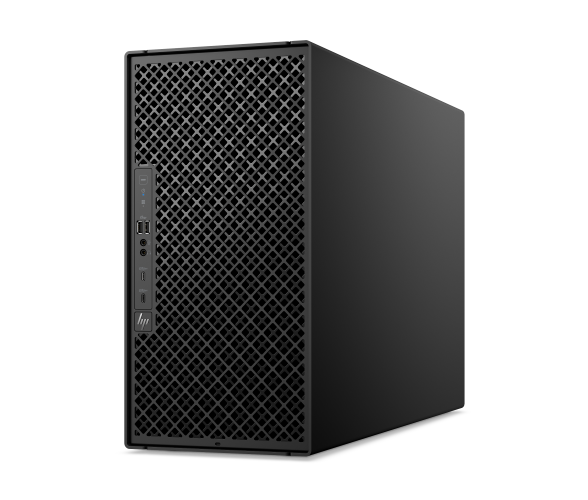 HP ZGX FuryNVIDIA GB300 | 252 GB | 76 GB Fits | ≤ 2008 tok/s | 4-bit | Price from the manufacturer | |
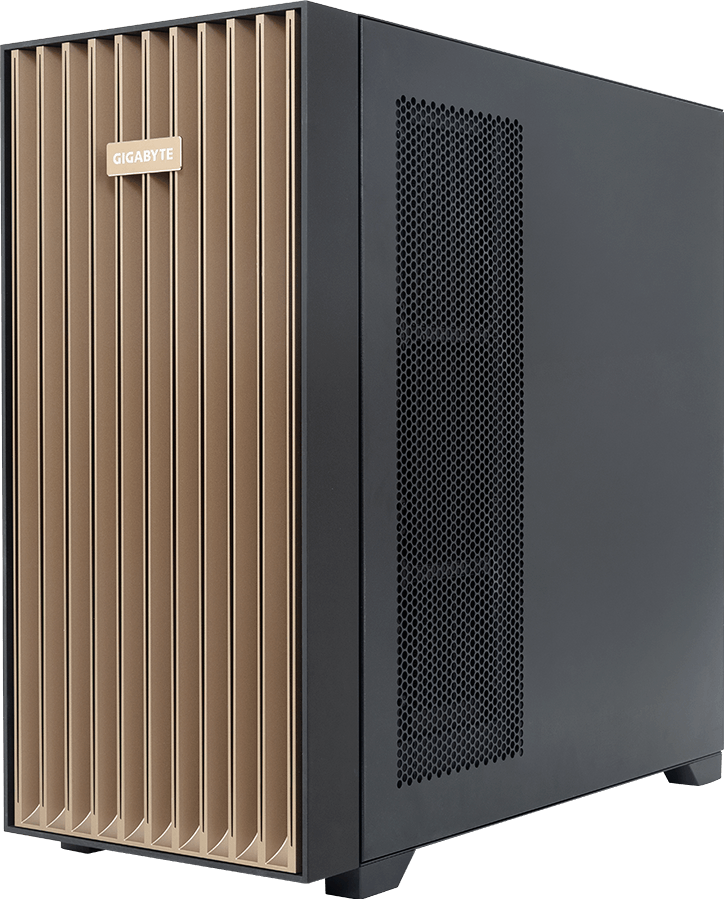 GIGABYTE W775-V10-L01NVIDIA GB300 | 252 GB | 76 GB Fits | ≤ 2008 tok/s | 4-bit | Price from the manufacturer | |
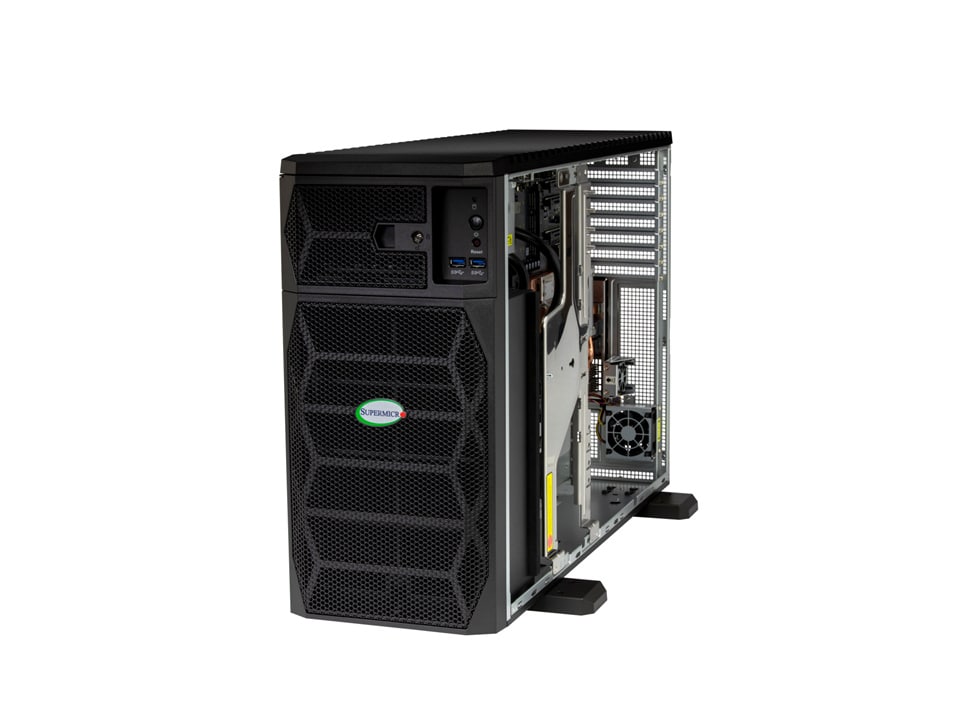 Supermicro Super AI Station · ARS-511GDNVIDIA GB300 | 252 GB | 76 GB Fits | ≤ 2008 tok/s | 4-bit | Price from the manufacturer | |
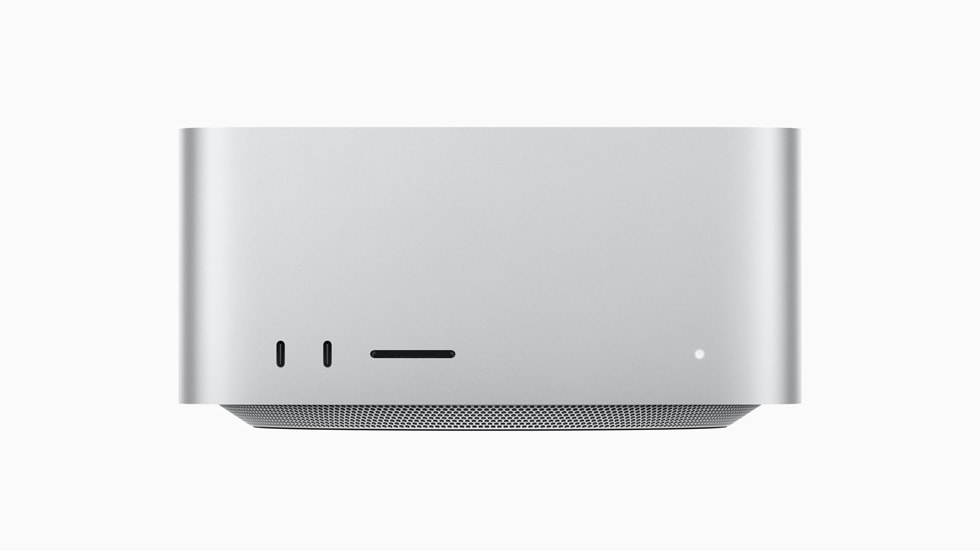 Apple Mac Studio · M3 UltraApple Silicon | 96 GB | 80 GB Fits | ≤ 232 tok/s | 4-bit | Price from the manufacturer | |
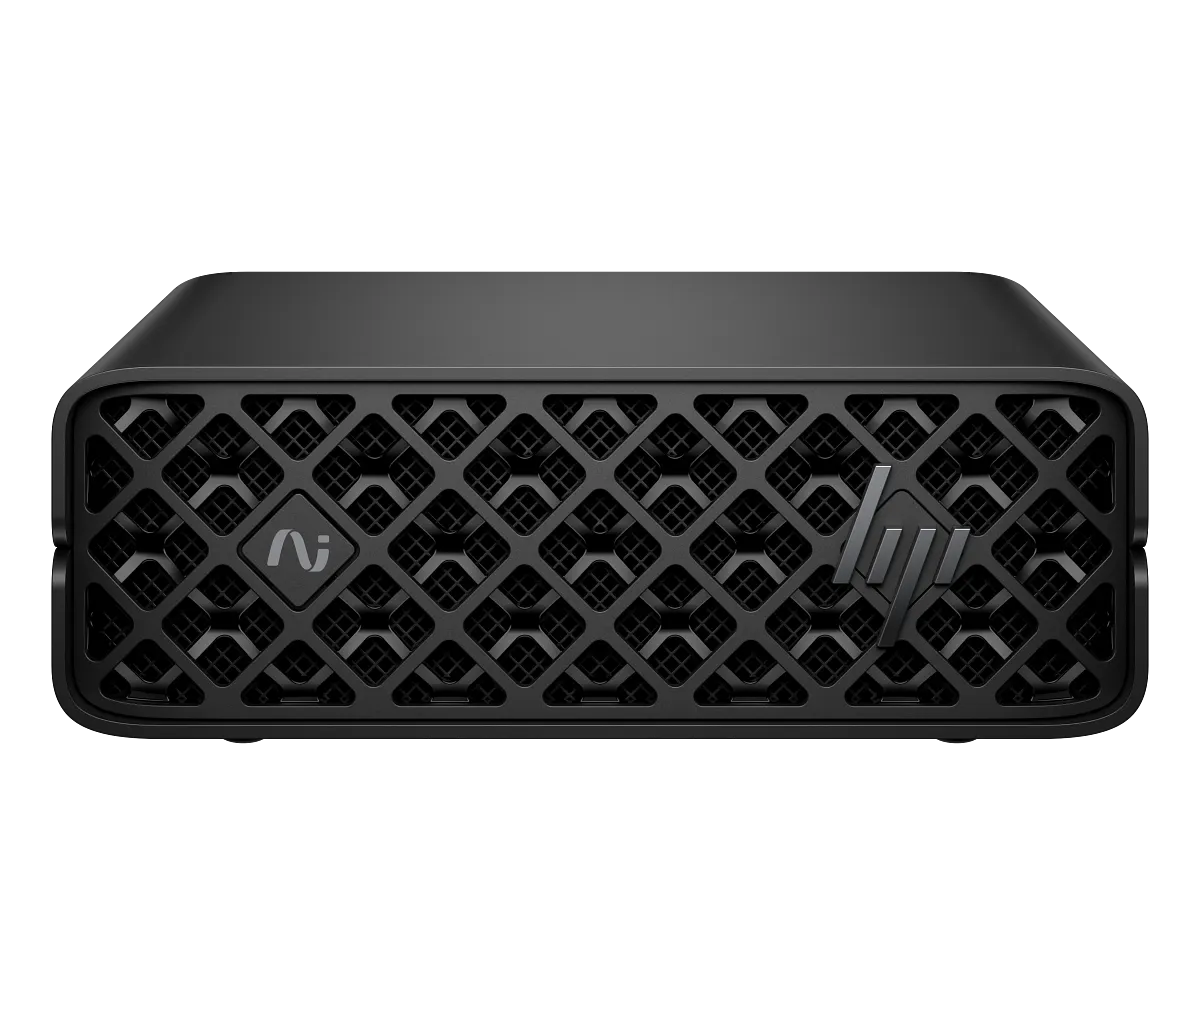 HP ZGX Nano G1nNVIDIA GB10 | 128 GB | 80 GB Fits | ≤ 77 tok/s | 4-bit | Vendor-listed validationSGLang · MXFP4 | Price from the manufacturer |
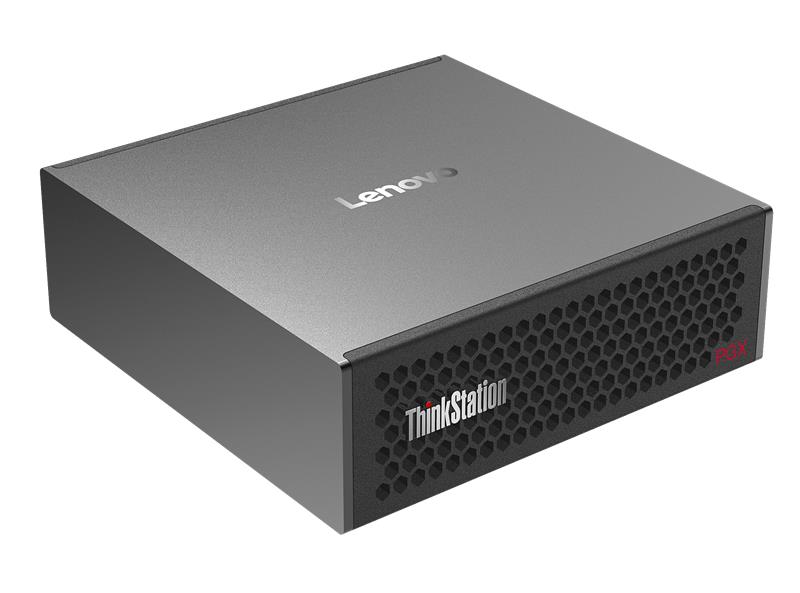 Lenovo ThinkStation PGXNVIDIA GB10 | 128 GB | 80 GB Fits | ≤ 77 tok/s | 4-bit | Vendor-listed validationSGLang · MXFP4 | Price from the manufacturer |
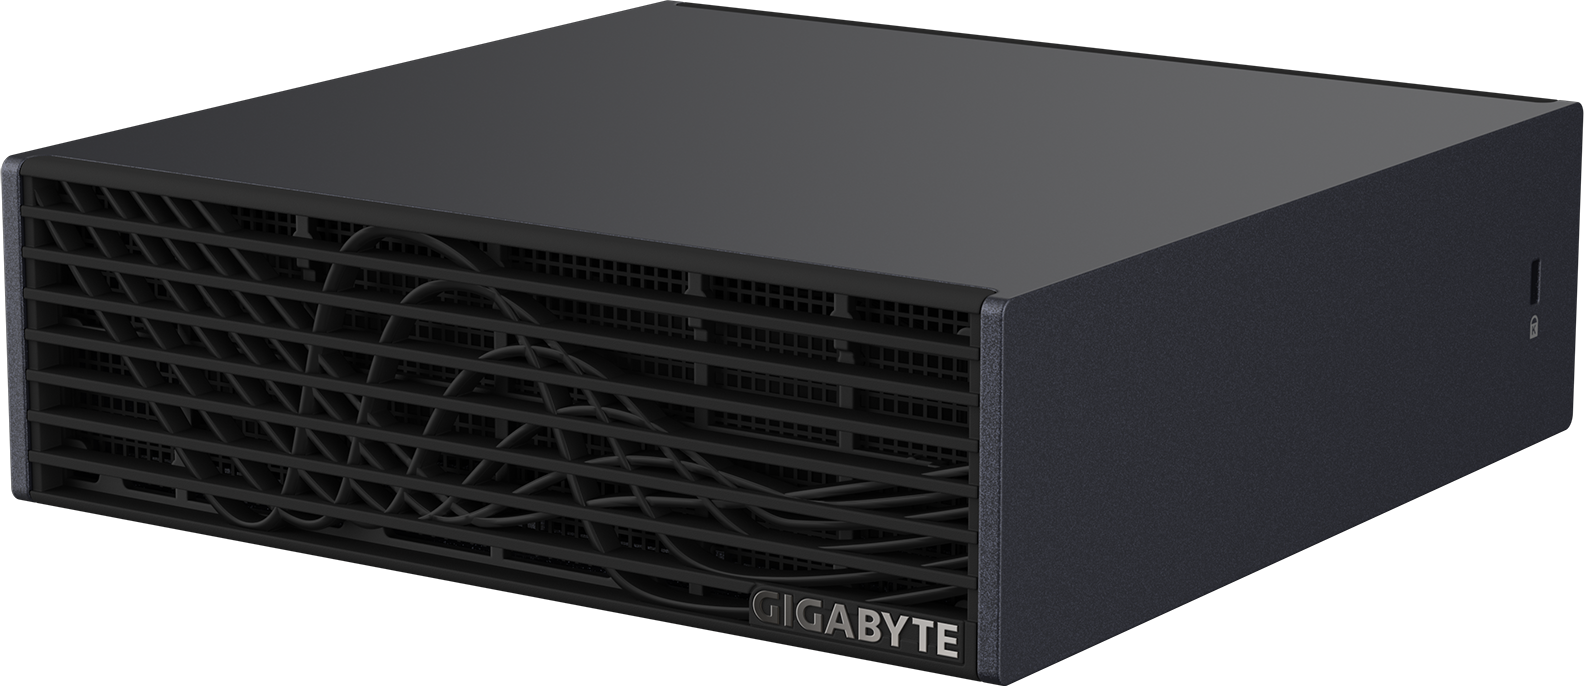 GIGABYTE AI TOP ATOMNVIDIA GB10 | 128 GB | 80 GB Fits | ≤ 77 tok/s | 4-bit | Vendor-listed validationSGLang · MXFP4 | Price from the manufacturer |
 AMD Ryzen AI HaloAMD Ryzen AI Max | 128 GB | 80 GB Fits | Bandwidth not in record | 4-bit | Price from the manufacturer | |
 HP Z8 Fury G6iNVIDIA RTX PRO | 96 GB | 76 GB Fits | Bandwidth not in record | 4-bit | Vendor support statementOllama / llama.cpp · MXFP4 | Price from the manufacturer |
 Lenovo ThinkStation P7NVIDIA RTX PRO | 96 GB | 76 GB Fits | Bandwidth not in record | 4-bit | Vendor support statementOllama / llama.cpp · MXFP4 | Price from the manufacturer |
 HP Z2 Mini G1aAMD Ryzen AI Max | 128 GB | 80 GB Fits | Bandwidth not in record | 4-bit | Price from the manufacturer | |
 Apple Mac Studio · M5 UltraApple Silicon | 96 GB | 80 GB Fits | Bandwidth not in record | 4-bit | Preorder · price from the manufacturer |
SGLang · MXFP4
openai/gpt-oss-120bNVIDIA source Ollama / llama.cpp · MXFP4
openai/gpt-oss-120bNVIDIA source About 69 GB for the weights at 4-bit, plus the KV cache and runtime reserve: roughly 80 GB in total at 8K context and one request. Longer context and more simultaneous users need more.
In the Lab’s catalogue, the Framework Desktop · Ryzen AI Max+ (≈ $3.4k, Supplier list price · United States · Sept 2026) passes the memory screen at 4-bit.
The Lab has no measured run yet. The memory-bandwidth ceiling for one request is ≤ 77 tok/s on the NVIDIA DGX Spark; real single-stream speed lands below the ceiling.
Head to head
NVIDIA DGX Spark vs Apple Mac Studio · M3 Ultra NVIDIA DGX Spark vs Apple Mac Studio · M5 Ultra NVIDIA DGX Spark vs Framework Desktop · Ryzen AI Max+ NVIDIA DGX Spark vs MINISFORUM MS-S1 MAX NVIDIA DGX Spark vs HP Z2 Mini G1a NVIDIA DGX Spark vs AMD Ryzen AI Halo Framework Desktop · Ryzen AI Max+ vs Apple Mac Studio · M3 Ultra Framework Desktop · Ryzen AI Max+ vs Apple Mac Studio · M5 Ultra HP ZGX Nano G1n vs HP Z2 Mini G1a