Power rating
Published detail240 W external adapter capacity. [1]
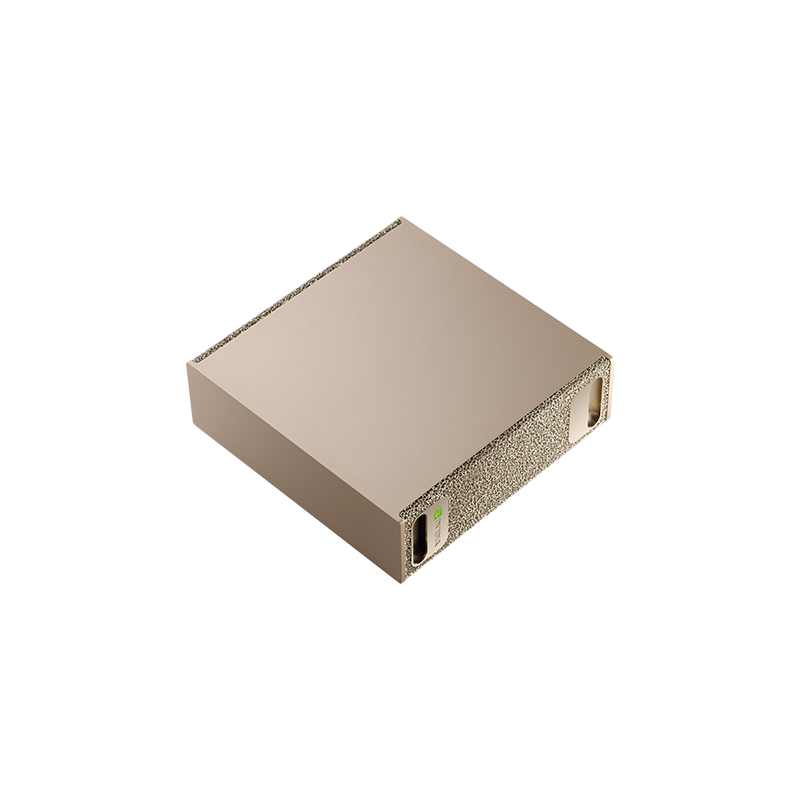
Manufacturer product image. The selected configuration may vary.
 Desktop AI system
GB10 Grace Blackwell Superchip
Lenovo’s compact GB10 offering for local AI development and experimentation.
Compared withNVIDIA DGX Spark
BEFORE IT ARRIVES
What this configuration needs on your premises.
A compact desktop office candidate. Lenovo’s short specification lists the adapter capacity but does not settle ventilation clearance or noise under continuous AI load.
240 W external adapter capacity. [1]
Regional input voltage, current and connector are not verified. Check the supplied power unit and installation manual.
No machine-specific branch-circuit requirement verified. Check the nameplate, regional cord and other loads on the same circuit.
Active air cooling with fans and a heatsink. Lenovo provides separate replacement procedures for these assemblies on machine types 30KL / 30KM. [2]
Whole-system ambient temperature and humidity limits are not verified. A power-supply temperature limit is not a system limit.
No comparable noise measurement under an AI workload verified. Ask for dB(A), distance, workload and ambient conditions; audition it before placing it beside people.
ACTUAL CONSUMPTION
PSU capacity, chip TDP and measured consumption describe different things. Only measurements with a stated configuration and test method appear here.
No attributable wall-power test for this configuration was established in this review. Measure at the outlet with the exact model, workload, runtime and power mode recorded.
Plan for the computer and its power supply to heat the room. Check ventilation during long jobs and when several machines share a small office.
Lab planning guidance. Office suitability depends on the installed configuration, shared circuits, heat removal and acceptable noise; a workstation label alone does not settle it.
Enter average power at the wall for the hours you are modeling, or an explicit planning assumption. Supply wattage and chip TDP are not consumption measurements.
Add wall power to calculate a scenario.
Scenario only. Hours outside this period are excluded: include idle time for an always-on system. Displays, networking, UPS losses and room air conditioning are extra. Heat assumes the computer and power supply release their heat into this room; it does not size a circuit or an HVAC system. Currency selects your tariff’s unit, with no conversion.
Manufacturer documentation and attributed first-hand hardware inspections, scoped to the named model or configuration. “Not verified” identifies a gap in this review, not a claim that the manufacturer has no documentation. Installation assessments are the Lab’s interpretation.
Keep sensitive processing on your infrastructure. Inspect every connection in the complete stack.
Control access, connectivity and updates. A local machine still needs a secure deployment.
Generate tokens on your own compute. Understand the full cost of the useful work it delivers.
SHARED WORK AROUND THIS PLATFORM
Reference-platform guidance and field records. Exact OEM configurations need their own validation.
 Understand TechField record
UT’s move from rented cloud GPUs to machines in its own office, and the engineering record behind it.
 NVIDIA · indexed by the LabRecipe
NVIDIA’s Open WebUI and Ollama guide, connected to the hardware and operating questions it raises.
NVIDIA · indexed by the LabRecipeConnect applications to a model server on a GB10 or GB300 reference platform using vLLM.
THE PLATFORM BEHIND THE MACHINE
8 catalog configurations
BEYOND THE SPECIFICATION
Published guidance and checklists to help you investigate the full deployment.
UT’s reported journey across serving stacks, hardware integration and customer feedback. A starting record for the decisions and evidence still to publish.
An operator-reported startup observation from UT’s GB10/GB300 work. The next step is to identify the exact configuration and separate the startup phases.
An execution agent and confidential engineering test assets show how on-premises AI extends beyond office applications.
THE CONFIGURATION
ON YOUR PREMISES
BEFORE YOU CHOOSE
Specifications vary by configured SKU and region.
Managed deployment through UT needs a compatibility and support review.
Manufacturer specificationsHelp improve this record. Suggest a correction
IN THE FIELD
Operating records from customers, contributors and the Lab.
In an office, a factory, an engineering lab or beside your test equipment. Share a deployment and keep the people behind it credited.
Contribute a deploymentTHE SHARED TECHNICAL LIBRARY
Supplier recipes, community experience and UT’s deployment lessons, connected to the hardware.
NVIDIA documents enterprise lifecycle integration and custom installation patterns.
Example tools are not preinstalled. Adapt to your management system and check the documented support boundaries.
NVIDIA’s model-serving playbook.
Check the selected NIM profile, image digest, memory use and readiness time.
NVIDIA’s vLLM setup reference.
Pin the container and test your model, prompt lengths and simultaneous requests.
Loading updates…
MEMBER RATINGS · SELF-DECLARED, NOT MEASURED
One rating per member, tied to a Lab profile. Stars count immediately; written verdicts are published after a quick review by the Lab team. A rating is an opinion about fit for a job, not a benchmark.
THE PEOPLE BEHIND THE MACHINES
Questions, ideas and experience from putting AI machines to work. You do not need a finished deployment to contribute.
Loading the discussion…
THE MACHINE × THE MODEL × THE WORKLOAD
Connect the model, serving stack, workload and cost of operating this box.
| Model | Serving configuration | Capacity planning | Evidence | Inspect |
|---|---|---|---|---|
| MXFP4 | Vendor-listed validation | |||
| MXFP4 | Vendor-listed validation | |||
| NVFP4 | Vendor-listed validation | |||
| FP8 | Vendor-listed validation | |||
| FP8 | Vendor-listed validation | |||
| NVFP4 | Vendor-listed validation |
Mutable container tag; pin its digest and model revision.
Reference-platform evidence does not establish exact-OEM performance.
Each measured result belongs to one box configuration, one model, one serving stack and one workload. Publish latency, per-stream speed, request rate, errors and task quality together.